 pepe
Ramp: finding where the target stops keeping up
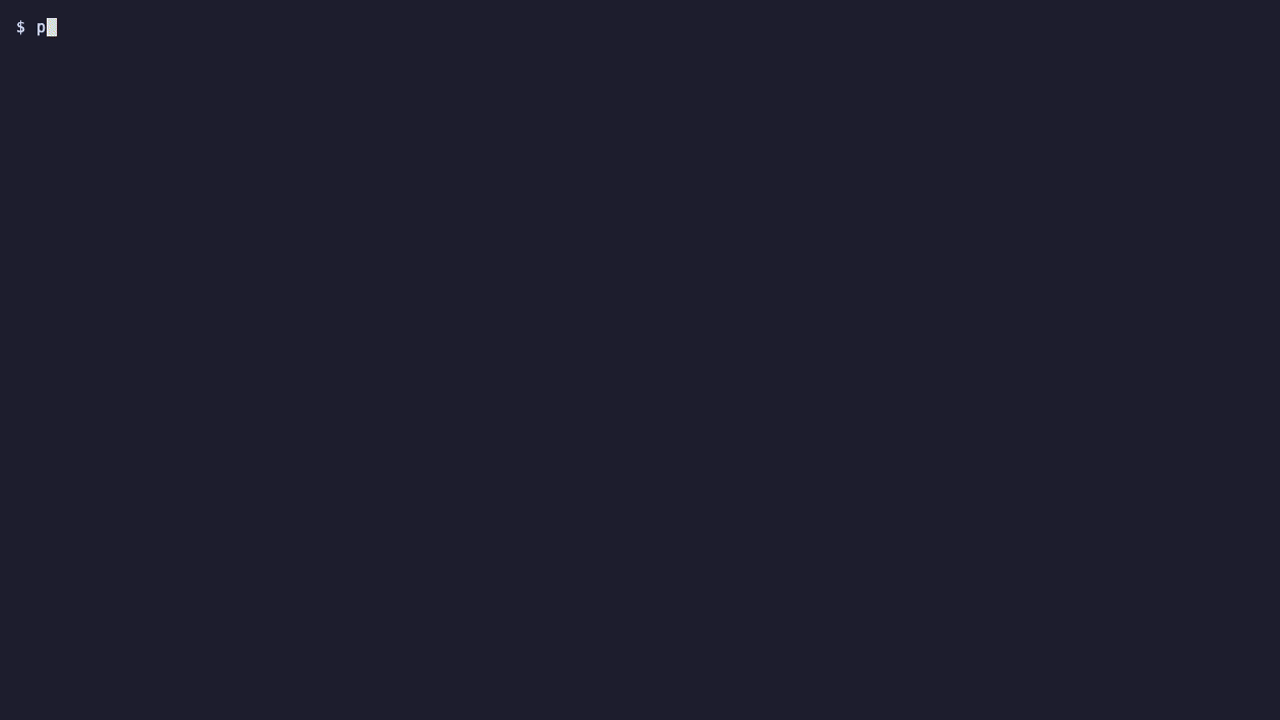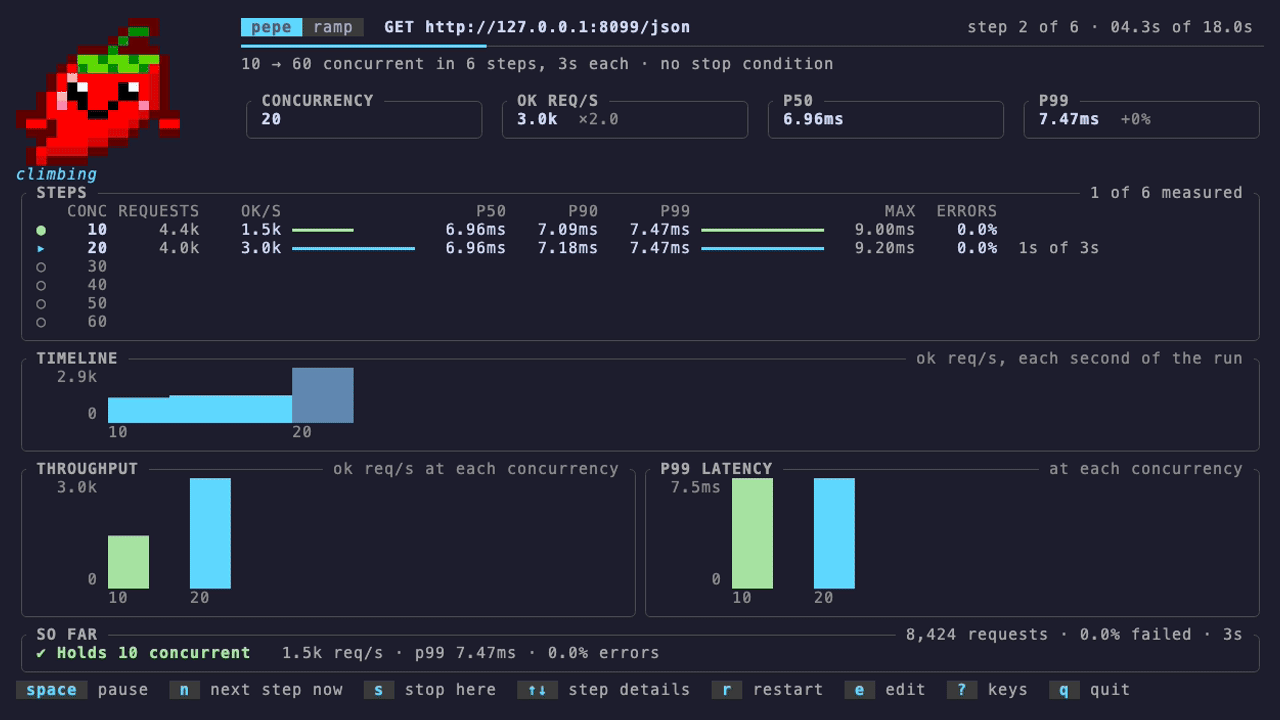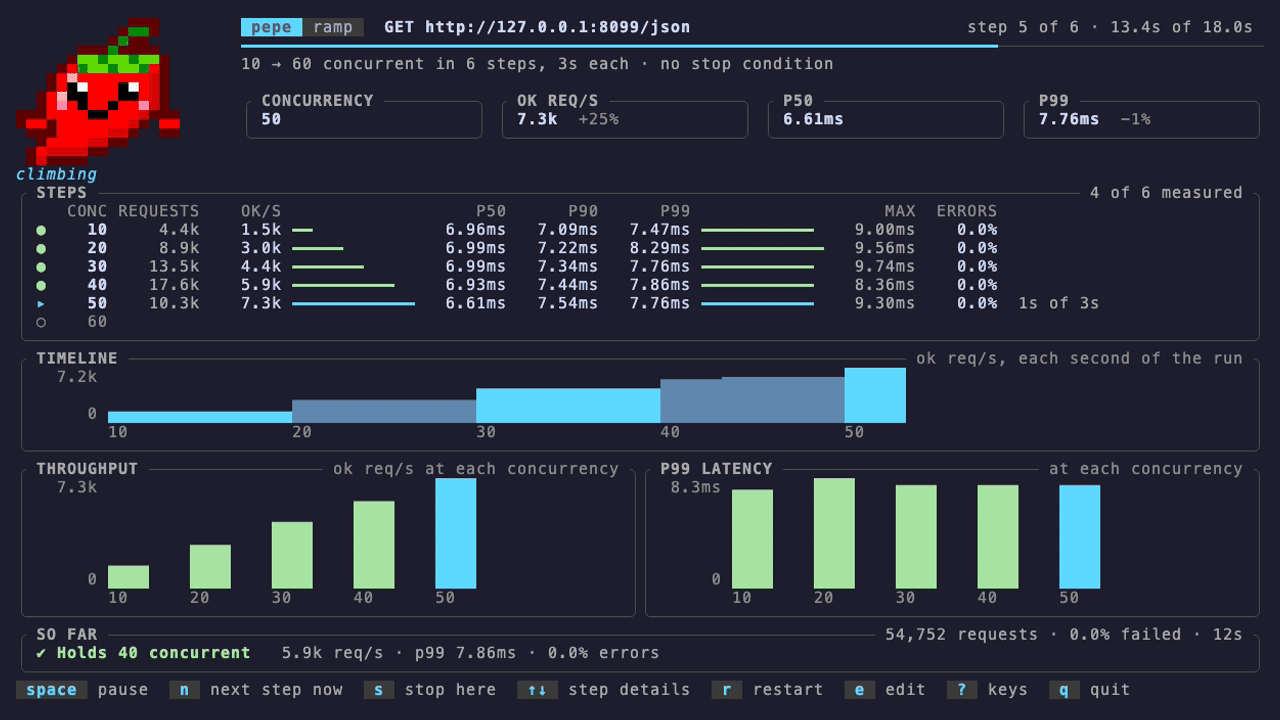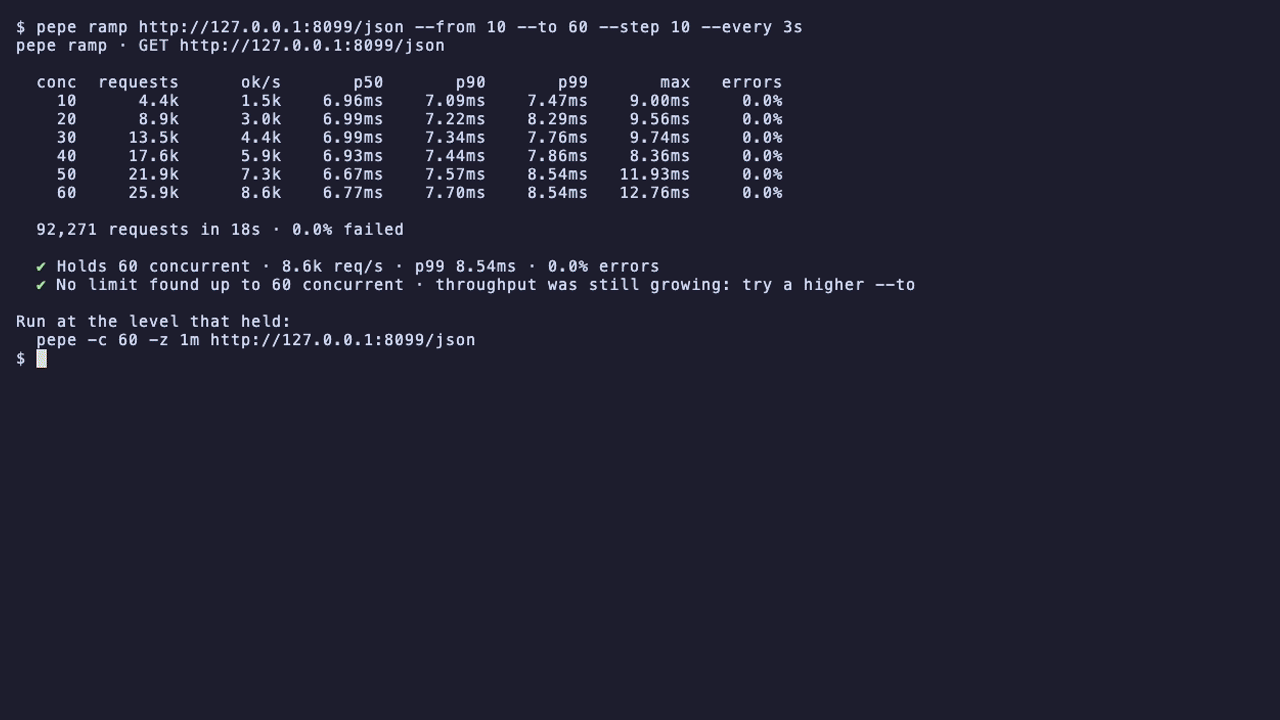
pepe ramp raises concurrency step by step, measures each step on its own, and says where the target holds, where it stops scaling and where it breaks.
pepe ramp https://example.com --from 10 --to 200 --step 10 --every 15s
pepe ramp https://example.com --until 'p99 > 500ms' --until 'errors > 1%'
pepe ramp https://example.com --json > ramp.json
Flags
| Flag | Default | What it does |
|---|---|---|
--from, --to, --step | 10, 100, 10 | Concurrency of the first step, the last, and what's added between |
--every <TIME> | 10s | How long each step is held |
--until <CONDITION> | End the ramp once a step crosses a limit: p50 > 100ms, p99 > 2s, errors > 1%; repeat for several |
-m, -d, -H and the other request options work as they do without ramp; -n, -z and -c don't apply, since the ramp sets its own load and length. Without a URL, the setup screen opens in Ramp mode. The [ramp] table of pepe.toml gives the same defaults (Config file).
The screen
Each step is a row: throughput (successful responses per second), p50, p90, p99, the slowest request, errors, and a note when something changes. Below it, the run second by second, throughput and p99 at each concurrency, and the result: the level that held, where throughput stopped following the load, where it broke, and the command for a steady run at the level that held. Throughput counts successful responses only, so a target that sheds load quickly doesn't look fast.
The capacity estimate
Once four clean steps are in, a saturation curve (the Universal Scalability Law) is fitted to throughput against concurrency, and the result states the capacity read off it: "Capacity about 3.0k req/s · reached around 30 concurrent · median latency doubles around 34". When the curve is still climbing at the last step but has begun to bend, the estimate says so ("Capacity beyond the ramp … past the ramp's 50"); when it hasn't bent at all, no number is given, because none would be honest. The estimate is kept only when the curve reproduces every measured step within 25%.
Keys
| Key | Action |
|---|---|
↑ ↓ | Pick a step and see everything measured about it; esc goes back to following the run |
space | Pause or resume; a step's clock stops while paused |
n | End this step now and go on to the next |
s | Stop the ramp here and keep the results |
r / e | Run again / back to the setup screen |
? | Show all keys |
q / Ctrl-C | Quit; the table and the result are printed to your shell |
The report
--json runs the ramp without a screen and prints every step, the findings, and capacity (requests_per_second, concurrency, extrapolated, latency_doubles_at_concurrency; null when the curve hadn't bent), plus holds_concurrency, the level that held. Piped without --json, the table and the result are printed as text. pepe schema ramp prints the report's JSON Schema, and pepe compare holds two ramp reports against each other by their capacity and the level that held (Compare). --fail-if applies to the whole ramp's requests (Output).