pepe
An HTTP load generator with a live dashboard, built to cost less than the server it tests. Load-test a URL, ping it to see where the time goes, ramp to find the capacity, and read the result as a verdict or a JSON report.
curl -LsSf https://pepe.mhaimdat.com/install.sh | sh
pepe https://example.com
To ~/.local/bin, with tab completion and man pepe. Later: pepe self-update.
powershell -ExecutionPolicy Bypass -c "irm https://pepe.mhaimdat.com/install.ps1 | iex"To ~\.local\bin, with tab completion for PowerShell. Later: pepe self-update.
brew install omarmhaimdat/pepe/pepemacOS and Linux.
nix run github:omarmhaimdat/pepe -- https://example.comOr keep it: nix profile install github:omarmhaimdat/pepe.
docker run --rm -it ghcr.io/omarmhaimdat/pepe https://example.comA few megabytes, linux/amd64 and linux/arm64.
cargo install --locked --git https://github.com/omarmhaimdat/pepeSigned binaries for every platform are on the releases page; every way to install, in the docs.
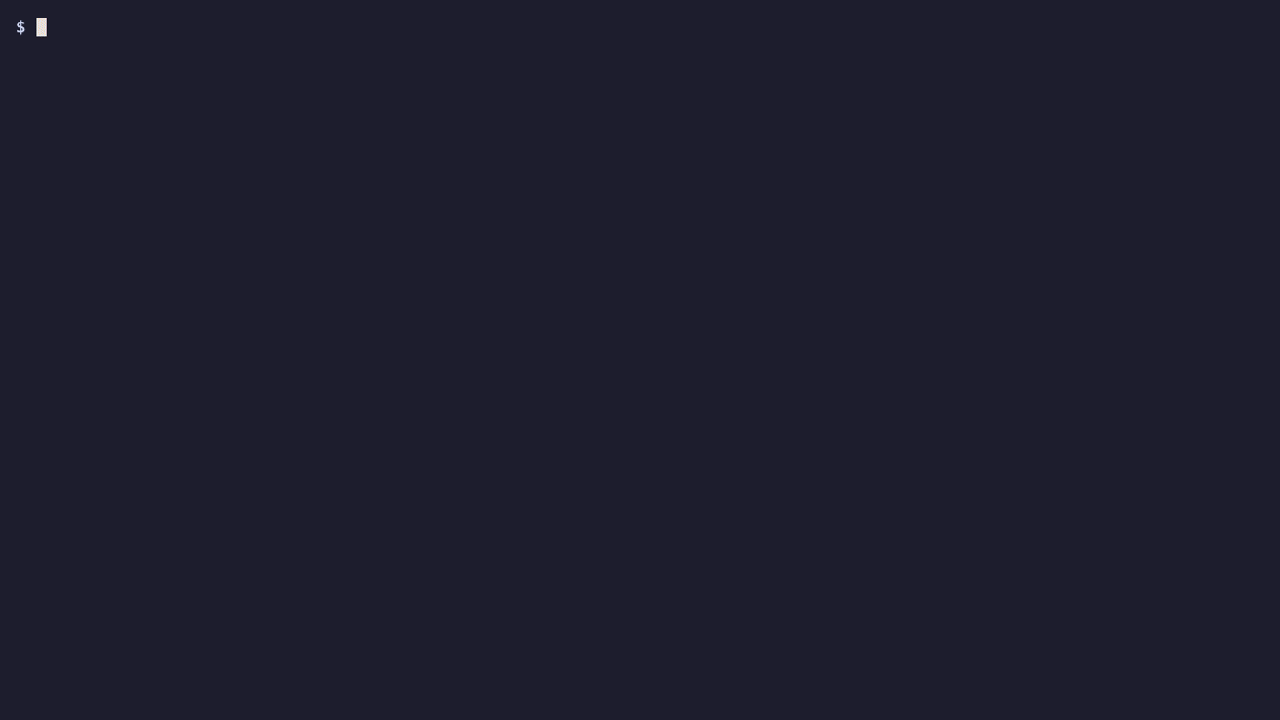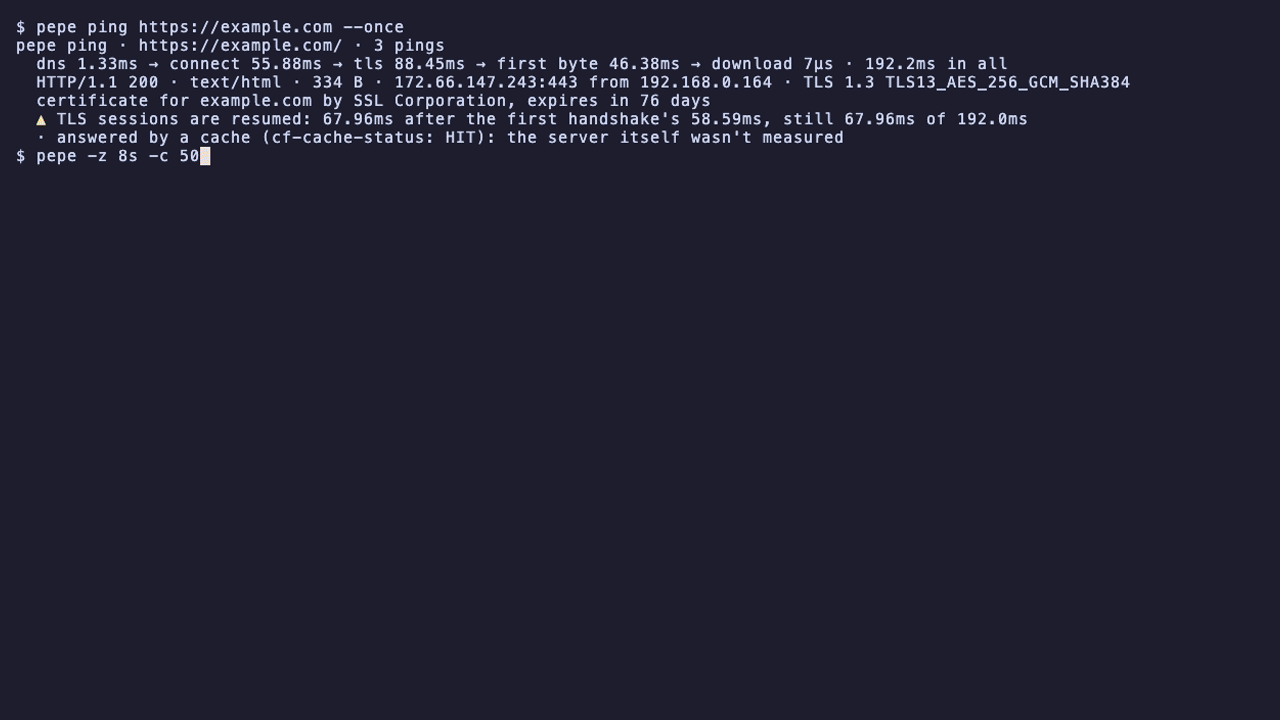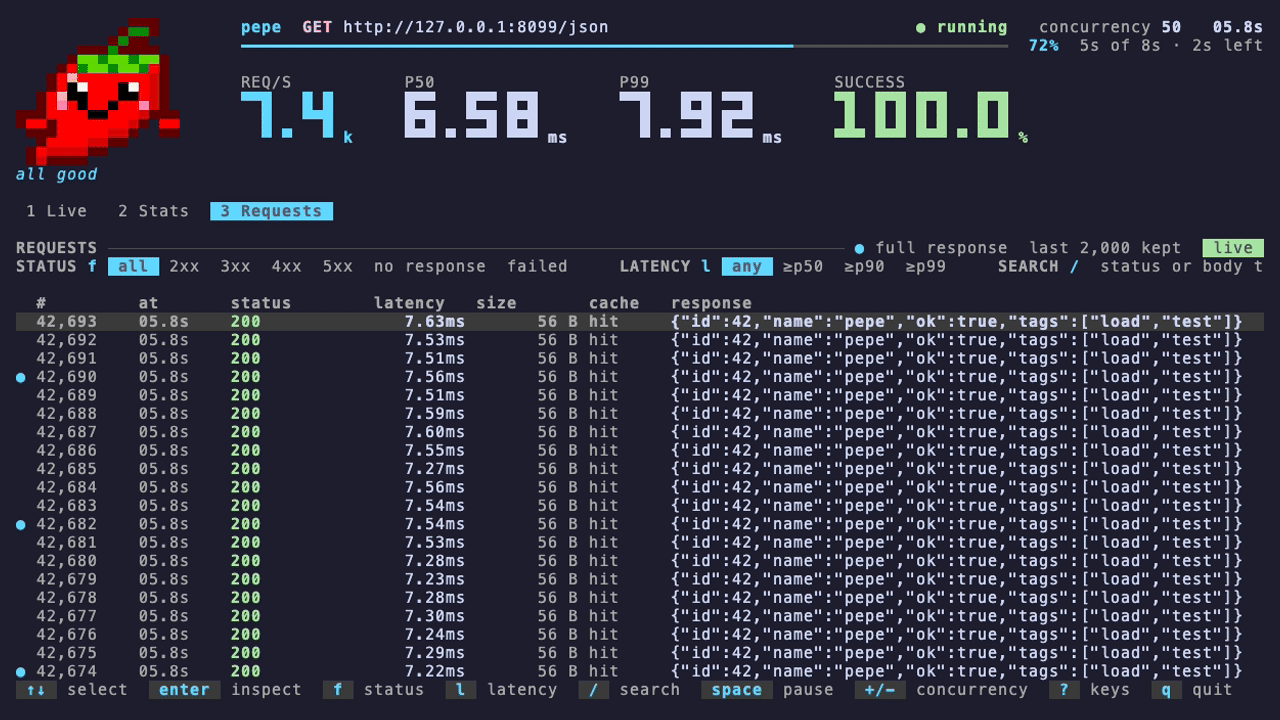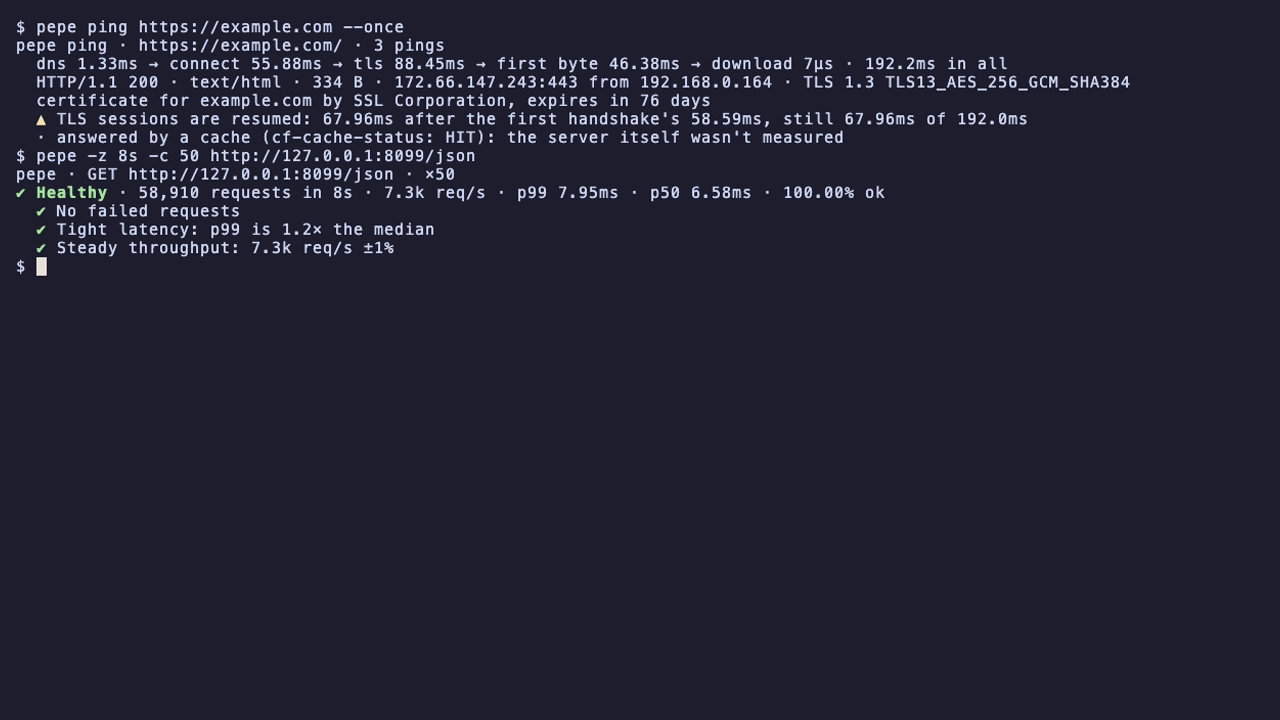
Load test
pepe URL: latency, throughput and errors live; pause, change the concurrency, open any request; a verdict when it ends.
Pingpepe ping URL: a request a second split into DNS, connect, TLS, first byte and download, on a graph, with what to look at.
Ramppepe ramp URL --to 200: raise the load step by step, find the level that held and the capacity.
Comparepepe compare before.json after.json: what moved between two runs, as a verdict, a badge and a card.
OpenAPIpepe api openapi.yaml: every endpoint of a spec under load at once, which are slow, which fail.
Flowspepe flow checkout.toml: a sequence of requests, each step fed by the one before.
Replaypepe replay access.log: an access log's URLs in their real proportions, sent at another host.
nginx logspepe logs access.log: the request rate now against each minute, hour and day, paths, errors and lines.
CI, scripts and agentsA GitHub Action, --fail-if 'p99 > 300ms', a versioned JSON report with a schema, and the modes as MCP tools with guardrails.